Building digital services for unreliable networks

Yamila FigueroaWebxya
Designing for unreliable networks is more than making pages load faster. Resilient services keep essential tasks working on slow, unstable connections.
Introduction
A person completes a form, reviews the information, and presses Submit just as the connection disappears. From the system’s point of view, this may be a network error. From the user’s point of view, the problem is much harder to interpret: was the request received, was the information saved, is it safe to try again, and will doing so create a duplicate? If the page reloads, there is also the more immediate concern of whether twenty minutes of work are about to disappear.
This is where unreliable connectivity stops being only an infrastructure problem and becomes part of the product experience. A service that works well only while the network behaves predictably is making an assumption that may be invisible during development but very noticeable in use.
In Why “Mobile First” isn't enough in humanitarian contexts, we looked at the broader conditions that shape digital access beyond screen size. Connectivity deserves closer attention because it affects almost every layer of a digital service: what can be downloaded, what information can be trusted as current, when work can be saved, how actions are confirmed, and what the interface should communicate when the system cannot know exactly what happened.
For teams that design for low bandwidth, the objective is not necessarily to make every feature work completely offline. In many products that would be unrealistic, unnecessary, or even unsafe. A more useful goal is to identify which parts of the experience need to remain dependable as network conditions deteriorate, and then design the product so those tasks can continue, pause, recover, or fail clearly rather than simply collapsing.
Connectivity isn't binary
Digital products often reduce network state to a simple pair: online or offline. The distinction is useful, but it describes only the extremes of what users actually experience.
A device can be technically online while a request takes thirty seconds to complete. It may have enough connectivity to retrieve the initial HTML but not enough to download a large media file or complete a later API request. It can switch networks during a transaction, experience temporary packet loss, or remain connected to a congested network that is effectively unusable. In other cases, the connection may work perfectly well while the cost of using it is high enough that people limit how often they load data-heavy services.
Those situations matter because they do not produce the same kind of failure. A slow connection may eventually complete an action, while an intermittent one may stop halfway through it. A congested network can make the interface feel frozen even when the device still reports that it is connected. An expensive connection changes the significance of every unnecessary image, script, or background request.
The practical implication is that connectivity behaves more like a spectrum of reliability than a boolean state. Browsers and operating systems can report whether a device appears to have network access, but that does not mean the next request will succeed, the server will respond, or the connection will remain available long enough to complete a task. Designing for unreliable internet therefore means accounting for transitions between conditions, not only for the moment when the device becomes fully offline.
Start with the critical user journey
Before deciding what to cache, synchronize, or make available offline, teams need to understand what the user is actually trying to accomplish and which parts of that journey would be costly to lose.
For an information service, resilience may mean keeping previously viewed guidance readable when the network disappears. In a registration flow, it may mean preserving answers locally so a person can return later without starting again. In a field-reporting tool, it may mean recording observations offline and synchronizing them when connectivity returns. A financial or identity-sensitive transaction, by contrast, may need an active server confirmation before the service can truthfully say that the action is complete.
These differences are important because they prevent resilience from becoming a purely technical exercise. The right architecture depends on what the task requires: which information can safely be reused, which data must be current, which actions can wait, which ones need immediate confirmation, and whether storing information locally is appropriate on the device in question.
The service does not need to preserve every feature under every condition. It needs to preserve the parts of the journey that matter most, and to make the limits of that preservation understandable.
Resilience starts by deciding which parts of a task must remain available when connectivity becomes unreliable, even if secondary content cannot.
Minimize what needs to travel over the network
Once the critical journey is clear, the next question is how much network activity that journey actually requires.
A page that depends on several API requests, multiple font files, high-resolution images, third-party scripts, and a substantial client-side bundle may perform perfectly on a stable connection, but each dependency creates another place where a constrained or intermittent network can slow the experience down or interrupt it altogether. In that context, performance work is not separate from resilience; the two begin to overlap.
The familiar techniques still matter: compression, responsive images, modern image formats, code splitting, lazy loading of secondary content, avoiding duplicate requests, limiting third-party scripts, and returning only the data a view actually needs. Their value, however, is broader than improving a speed score. Reducing unnecessary transfers lowers the number of conditions that must hold before the essential experience becomes available.
The same principle applies to application architecture. If a page can render important content on the server, making that content wait for a large client-side bundle may add fragility without adding equivalent value. If several API calls can be consolidated appropriately, the user has fewer points of failure. If an image is decorative, it should not determine whether instructions can be read or a form can be completed.
A low-bandwidth website does not need to look visually impoverished. The aim is to prevent secondary assets from controlling access to primary information.
Use progressive enhancement
Progressive enhancement offers a useful way to decide which capabilities belong in the foundation of the experience and which can be layered on when the environment supports them.
In a web context, that may mean starting with semantic HTML, meaningful links, native controls, server-rendered content where appropriate, and conventional browser behavior before introducing richer client-side interaction. JavaScript can still play an important role, and some application flows genuinely depend on it. The point is not to avoid modern frameworks, but to avoid making implementation convenience an unnecessary prerequisite for access.
This becomes particularly relevant under poor connectivity. A real link can still work when enhancement code is delayed. A resilient form has more options if hydration fails. Essential content rendered on the server can remain available even if secondary scripts never arrive.
The important architectural question is not whether every feature can survive without JavaScript, but whether the most important parts of the journey depend on layers that are especially vulnerable to network and device constraints. Progressive enhancement helps teams make that dependency visible before it becomes a failure mode.
Cache intentionally
Caching can make a service much more resilient, but only when teams are clear about what is being stored, for how long, and under what conditions it remains useful.
Static assets such as stylesheets, icons, interface scripts, and fonts are often natural candidates for longer-lived caching because their versions can be controlled. Stable reference content may also be useful to retain so previously accessed information remains available during an interruption.
Dynamic data is more complicated. A cached list of office locations may remain useful for some time, while a cached application status, eligibility decision, appointment slot, inventory count, or security-sensitive record can become misleading or unsafe if the user assumes it is current.
That means caching decisions need to consider more than performance. Teams may need to ask how old information can become before it creates risk, whether the interface should expose when it was last updated, whether the data is appropriate to store on a shared device, and what should happen when a newer version cannot be retrieved.
The answer may vary considerably within the same product. Documentation can remain useful for days, while a status screen may need a clear timestamp after only a few minutes. Sensitive data may not belong in persistent storage at all. Intentional caching means treating those differences as part of product design rather than applying one policy everywhere.
Design meaningful offline states
A full-screen message that says No internet connection is technically accurate, but it often tells the user very little about what they can still do.
When connectivity disappears, the interface should distinguish between the parts of the service that are no longer available and the parts that can continue. Previously loaded information may still be readable. A draft may still be editable. Navigation through cached content may remain possible, while only the final submission requires a live connection.
This is more useful than treating offline as a complete shutdown. A well-designed offline state can show when information was last updated, make clear that a draft is stored locally, and indicate which actions will need connectivity before they can complete.
The interface also needs to avoid promising capabilities it does not have. A message such as “We'll submit this when you're back online” is only appropriate if the system really has a reliable queue and synchronization mechanism. When it cannot guarantee that behavior, a more precise explanation is safer and more useful.
Offline design should therefore communicate the boundaries of the current state without hiding the parts of the task that remain possible.
Store and synchronize carefully
Allowing people to continue working locally sounds simple until local work has to meet remote state.
Saving a draft on the device is relatively straightforward. Synchronizing that draft later introduces harder questions. The same record may have changed on the server. A queued action may be sent twice. Several pending operations may depend on one another. Synchronization may succeed only partially. On a shared device, locally stored information may also create privacy risks that would not exist in a private-device model.
The right approach depends on the type of action. Append-only events can be comparatively straightforward because the service is adding new information rather than reconciling competing versions. Editable records introduce conflicts because two versions may both be valid from their own point of view. Critical transactions require even more care, since a locally recorded action is not necessarily equivalent to one that the server has accepted.
For that reason, resilient products often need to distinguish several states rather than collapsing everything into “saved” or “done”:
| State | What it means to the user |
|---|---|
| Saved locally | The work is preserved on this device but has not reached the server. |
| Waiting for connection | The action is queued and cannot synchronize yet. |
| Syncing | The service is attempting to send or reconcile the change. |
| Confirmed | The server has accepted the action and the service can treat it as complete. |
| Needs attention | Synchronization failed, conflicted, or requires a decision before continuing. |
These distinctions may look like technical bookkeeping, but they protect the user from false certainty. A service should not imply that something has been completed when it only knows that the information has been stored locally.
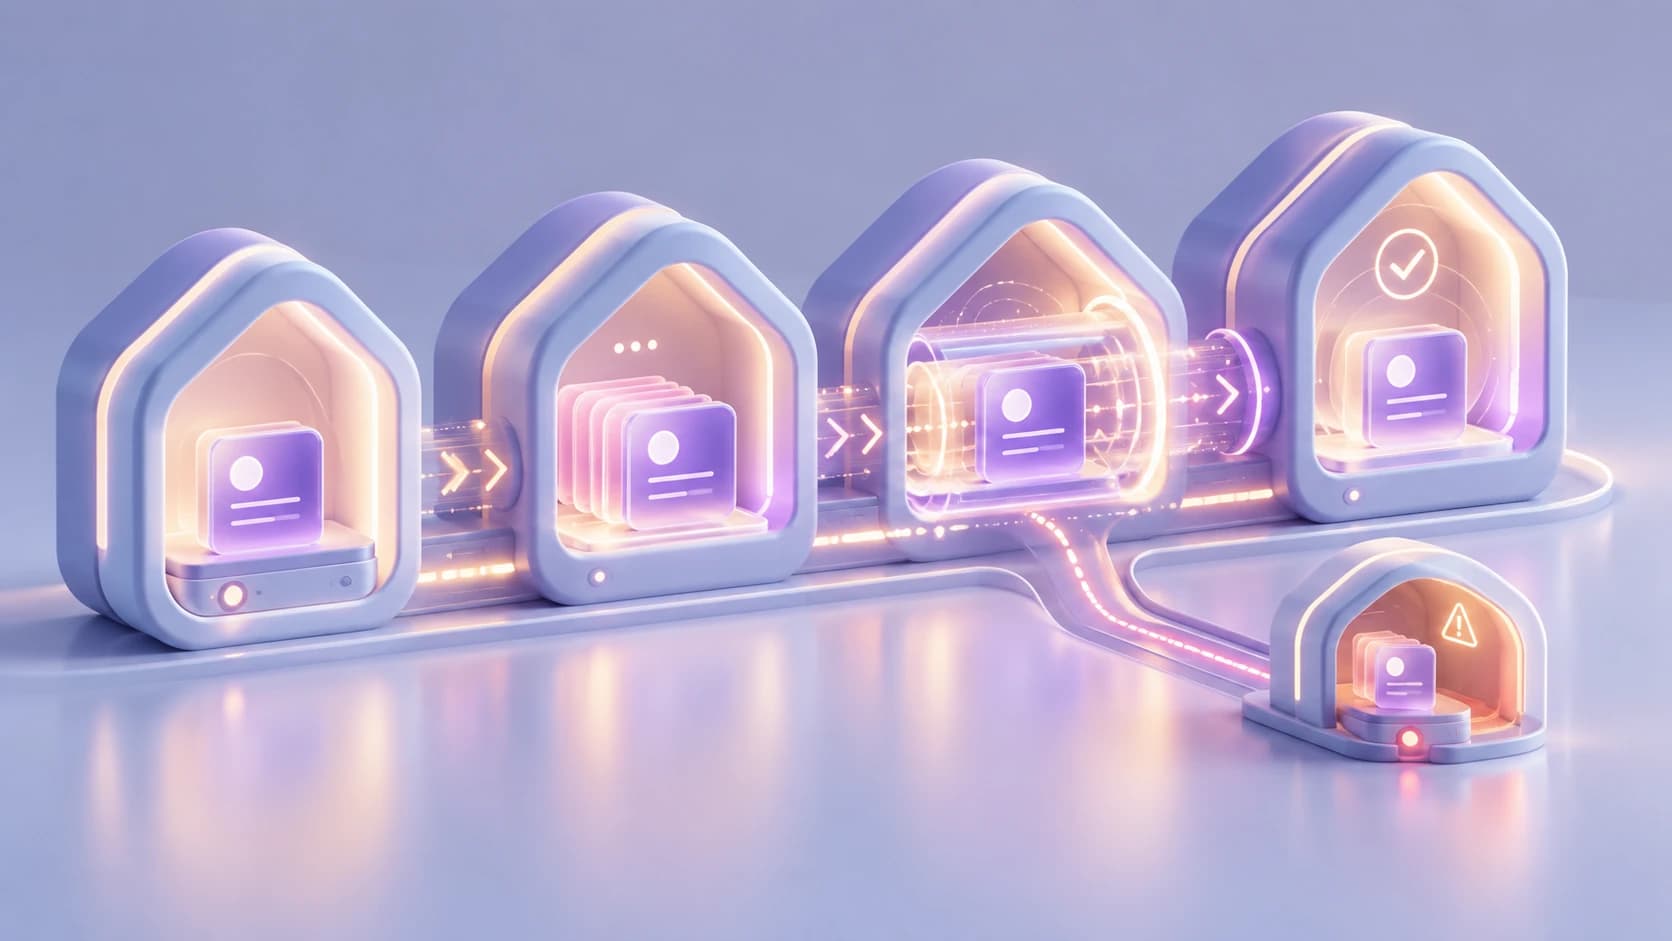
The same data can pass through several states before it is truly confirmed. Resilient synchronization makes those transitions, and any failed path, explicit.
Communicate network status clearly
Products often represent connectivity with a global icon: green for online, red for offline. That can be useful as ambient information, but it rarely answers the question users care about most, which is whether their work has actually been saved, sent, or confirmed.
Status information is usually more useful when it appears close to the action it affects. A draft might indicate that it is saved on the device. A queued request might show that it is waiting to sync. Previously retrieved information might include a “last updated” timestamp, while an action that could not be confirmed should say so explicitly and offer a safe next step when one exists.
The language matters because several states that sound similar are not interchangeable. Something can be saved locally without being synchronized, synchronized without being submitted successfully, or submitted without being confirmed. If the interface collapses those distinctions into a generic success message, it can create false certainty at exactly the moment when the system is least certain.
A resilient interface therefore needs to communicate the state of the user’s work, not only the state of the network.
Avoid making users repeat work
One of the most visible consequences of poor network resilience is repeated effort.
When a connection fails, a user should not have to re-enter information simply because the system did not preserve it. A long application should not return to the first step because the final request timed out. An upload should not automatically restart from zero because the network disappeared near the end. A draft should not vanish because the page refreshed unexpectedly.
Different products will solve this in different ways. Autosave, local drafts, resumable uploads, step persistence, idempotent requests, safe retry patterns, and carefully designed queues can all help. The common principle is that recovery needs to be considered as part of the task itself, not added later as an exception.
Repeated work has costs beyond frustration. It can consume additional data, battery, and time. It can introduce errors when people reconstruct information from memory, and it can increase abandonment when the task was already difficult or access to the device is limited. The more effort the user has invested, the more deliberate the service should be about protecting that progress.
Test under bad conditions
A service developed on broadband, modern laptops, localhost, and consistently responsive APIs can appear highly resilient without ever being placed under meaningful stress.
Testing needs to include the conditions the architecture claims to support. Network throttling is a useful starting point because it makes latency and limited throughput visible during development, but teams should also test requests that time out, connections that disappear halfway through an action, reconnection after several minutes, pages that load with only some assets available, and synchronization that resumes after a long interruption.
Device constraints matter as well. A low-memory phone may expose problems that network throttling on a powerful desktop does not. A service that behaves acceptably on a simulated slow connection may perform differently when packet loss, background activity, browser limitations, or older hardware are involved.
The objective is not simply to measure whether the page eventually loads. Teams also need to observe whether the user journey remains understandable while the system is degrading. Can a person tell that an action is pending? Is previously entered information still there? Does the interface recover when connectivity returns? Can the user distinguish stale information from current information? If the same request is retried, is duplication handled safely?
Testing resilience means thinking through the entire journey: where it can slow down, break, recover, and still allow the user to continue.
Resilience is part of UX
The work described in this article is often divided between disciplines. Performance may sit with engineering, caching with infrastructure, synchronization with application architecture, error messages with UX writing, and offline states somewhere between product and frontend development.
Users do not experience those boundaries. They experience whether the page loads, whether their work is preserved, whether the interface tells the truth about what happened, and whether they can continue when the network returns.
That is why resilience-first is useful as a design principle. It gives product, design, and engineering a shared way to evaluate the same experience: what happens to the essential task when the environment becomes less reliable than the one used to build and test it?
The answer will not always be full offline functionality. In one service it may be a lighter page, in another a preserved draft, a timestamp on cached information, a clearer pending state, or a retry mechanism that cannot create duplicates. What matters is that those decisions are made deliberately rather than left to whatever happens when the network fails.
Resilience does not require a product to eliminate every possible failure state. Networks will still disappear, requests will still time out, and some actions will still need a live connection before they can be completed safely. The quality of the experience depends on whether those moments remain understandable and recoverable, without turning a temporary infrastructure problem into lost work or an abandoned task.
- Digital Resilience
- Low Connectivity
- Offline First
- Performance
- Progressive Enhancement
Keep reading
NGOs do not need to solve every accessibility issue at once. Start with critical services, set a baseline, stop creating new barriers and build a roadmap.
Accessibility
Accessibility debt: the problem nobody talks about
Accessibility debt builds up when an inaccessible decision repeats across components, content, code and processes. The longer it spreads, the more it costs.
If these challenges sound familiar, let’s talk about your context.
Start a conversation