Building better digital products with limited resources

Yamila FigueroaWebxya
Limited resources do not have to produce lower-quality digital products. Stronger results come from narrowing scope and reusing what already works.
Introduction
A digital project can begin with a relatively simple objective and become complicated surprisingly quickly. An organization may start by planning a new website or service, then add a resource portal, multilingual content, CRM integration, analytics, advanced search, dashboards, automation, personalized experiences, and perhaps an AI feature that did not exist in the original brief. None of those requests is necessarily unreasonable on its own. The difficulty appears when they all begin competing for the same budget, timeline, and team.
When scope grows faster than resources, quality rarely disappears in one obvious place. It is more likely to erode across the project. Testing becomes shorter, content is reviewed less carefully, accessibility is postponed, components are created quickly instead of reused, and technical choices are made for immediate delivery rather than long-term maintenance. The product may still launch with an impressive list of features, but the organization inherits a system that is harder to operate than expected.
This is why organizations trying to build digital products with limited resources should resist the assumption that a smaller budget requires a lower standard. A more effective response is usually to reduce the number of problems being solved at once, then invest enough attention in the remaining ones to solve them properly.
That distinction matters. Reducing scope can mean fewer features, fewer integrations, fewer templates, or less custom development. Reducing quality means accepting confusing journeys, inaccessible interfaces, fragile technology, poor performance, or maintenance costs the organization cannot sustain. Those are not the same decision.
For organizations working with constrained budgets, small teams, or limited internal technical capacity, the most useful strategy is often not to ask how everything can be made cheaper. It is to decide what deserves to be built well first.
Limited resources are a prioritization problem
Limited resources are usually discussed in financial terms, but money is only one part of the constraint. Time, technical expertise, content capacity, stakeholder attention, testing capacity, and long-term ownership all affect what an organization can realistically support.
A team may have enough budget to build a feature but not enough staff to keep its content current. It may be able to launch an integration without having anyone who can troubleshoot it when the external service changes. A project may have development capacity but very little time from subject-matter experts, which means content decisions become a bottleneck instead.
These constraints become difficult when a backlog mixes fundamentally different kinds of requests. A critical user need can sit next to a preference from an internal stakeholder, a legacy requirement that nobody has revisited, and an idea that has never been tested with users. If all four are treated as equally important, the organization is not really prioritizing; it is distributing effort across everything.
A better approach begins by asking what each request contributes to the outcome the product is supposed to create. Some work will be essential. Some will be useful but deferrable. Some may solve a real problem only for a very small group. Other requests may exist because they sounded valuable during planning rather than because evidence shows that users need them.
For a team with limited resources, this distinction is not administrative. It determines whether the available budget produces a coherent product or a collection of partially solved problems.
Start with outcomes, not features
Feature requests often arrive in solution form. An organization says it needs a dashboard, a member portal, a chatbot, or a mobile application. Those requests may eventually be correct, but they skip an important question: what outcome is the feature supposed to create?
A dashboard might exist because regional teams cannot tell which cases require attention. A member portal might be proposed because people repeatedly ask staff to email them the same documents. A chatbot might be requested because users cannot find answers in the existing information architecture. Once the underlying problem is clear, the range of possible solutions becomes much wider.
That matters especially when resources are constrained. If the outcome is to help regional teams identify urgent cases, a carefully designed report or filtered view may be enough. If the problem is repeated document requests, a well-structured resource library might solve it without introducing accounts, authentication, permissions, password recovery, and all the maintenance that comes with a portal.
Thinking in outcomes does not mean rejecting ambitious features. It means earning them. A feature is valuable when it is the right response to a demonstrated need, not simply because it appears modern or because another organization has one.
This shift also makes prioritization easier. Teams can compare potential work against the same question: which option is most likely to improve the outcome we care about, and what does it cost to build and maintain?
Identify the smallest useful product
The language of MVPs is useful in some teams and unhelpful in others. Too often, “minimum viable product” is interpreted as a permission to release something incomplete, visually rough, inaccessible, or difficult to use, with the expectation that quality can be added later.
For organizations with limited budgets, a more useful idea is the smallest useful product: a version narrow enough to build properly, but complete enough to solve one meaningful problem.
Consider a resource library for an NGO. A useful first version may need clear categories, reliable search, accessible documents, responsive pages, and a content management system staff can actually use. Those capabilities may be enough to solve the main problem well. User accounts, personalized recommendations, saved favorites, advanced dashboards, and AI-assisted search can remain future possibilities rather than requirements for launch.
The discipline lies in resisting sideways expansion before the core experience has proved useful. A small product that solves one important task clearly can generate evidence, reveal real user needs, and create a foundation for future investment. A larger product that spreads the same resources across many unfinished capabilities may be harder to learn from because it is never clear whether problems come from the idea itself or from weak execution.
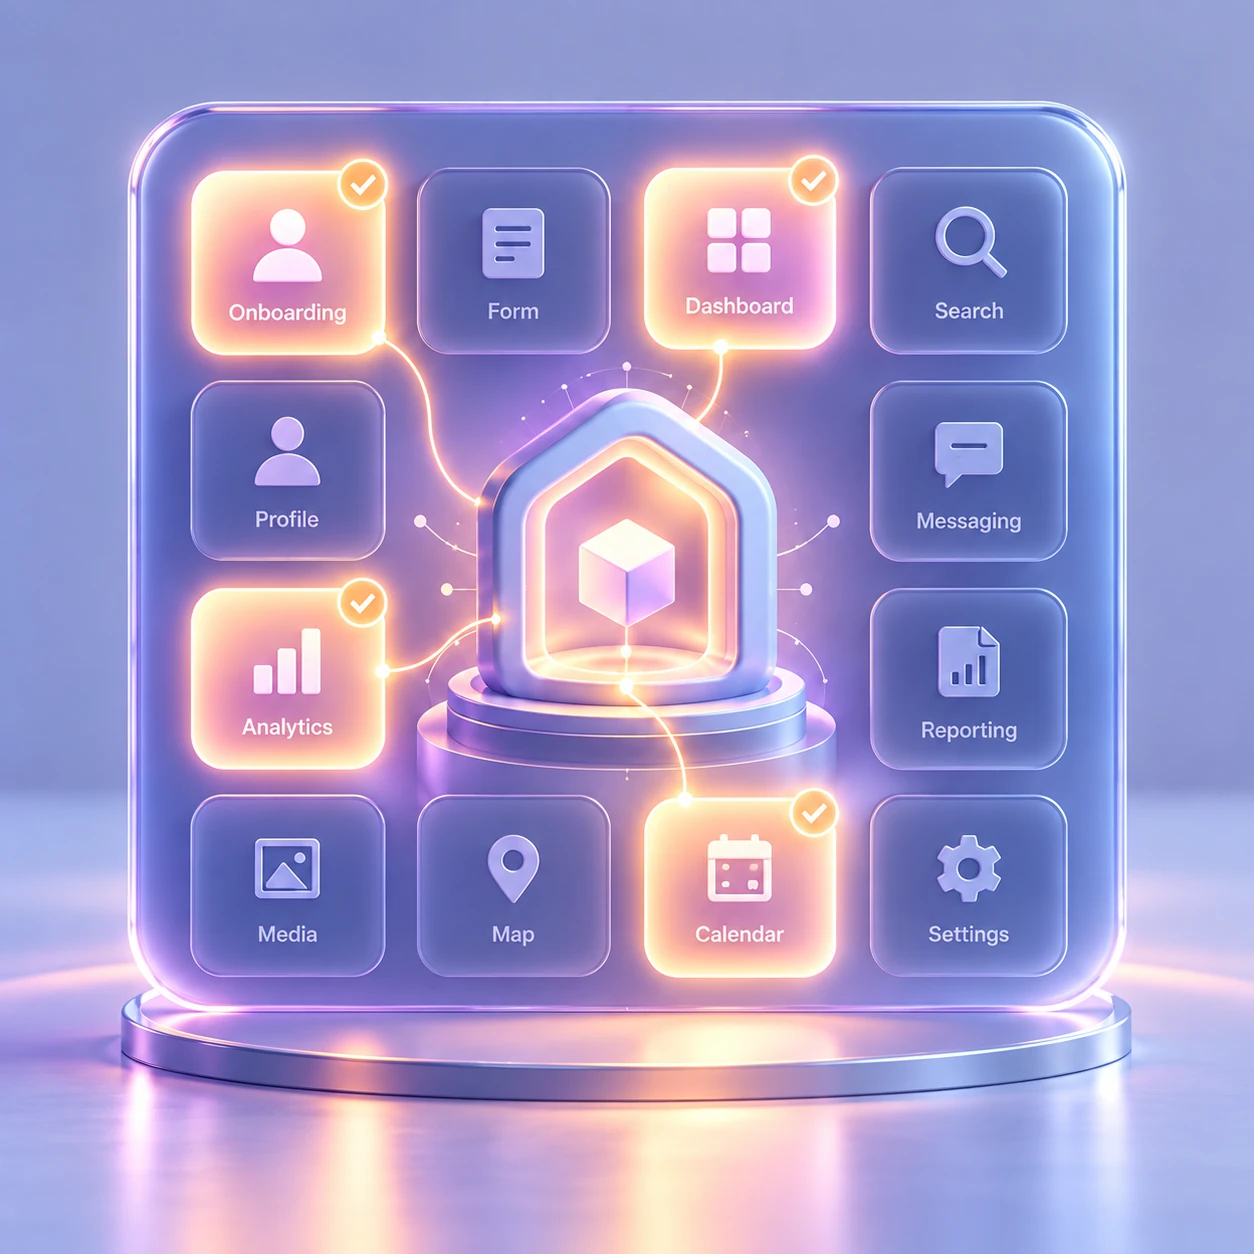
Reducing scope does not mean reducing quality. It means concentrating resources on the smallest version that can solve a meaningful problem well.
Prioritize critical user journeys
Once the product has a clearer scope, the next step is deciding where quality matters most.
Not every page or interaction has the same consequence. A campaign landing page, an internal information page, a donation flow, an application form, and an emergency resource finder all belong to the same digital ecosystem, but they do not carry the same weight for users.
Critical user journeys are the paths where failure has the greatest cost. Depending on the organization, that may mean finding essential information, submitting an application, registering for a service, donating, downloading a resource, or reaching the correct team.
These journeys deserve disproportionate attention because they are where design, content, accessibility, performance, and technical reliability converge. A visually impressive homepage cannot compensate for a donation flow that is confusing on mobile. A sophisticated portal is not successful if the form people need most is difficult to complete with a keyboard or on a slow connection.
Prioritizing journeys also helps teams decide how to allocate testing effort. Instead of attempting to polish every corner of a product equally, they can identify the interactions where failure would most directly prevent someone from achieving an important outcome.
This is one reason the broader qualities discussed in What Makes a Good Website in 2026? matter so much for constrained teams. Clarity, accessibility, performance, resilience, and maintainability are not decorative improvements. They protect the parts of a product people actually depend on.
Reuse before creating
Organizations often lose resources through repeated decisions rather than through one obviously expensive feature.
A new project defines its own spacing scale, button variants, form behavior, error messages, card layouts, typography rules, and navigation patterns. A second project makes similar decisions slightly differently. A third begins from another template entirely. None of these choices is individually catastrophic, but together they create more design work, more implementation work, more testing, and more inconsistency to maintain.
Reuse reduces that cost.
For a large organization, reuse may take the form of a mature design system with shared tokens, components, documentation, code libraries, and governance. For a smaller team, the useful version may be much lighter: a small set of design tokens, several reusable components, a few documented interaction patterns, and clear conventions for recurring content.
The scale should match the organization. Building an elaborate design-system platform for a team that maintains one small website would reproduce the same problem this article is trying to avoid: investing heavily in infrastructure the organization does not need.
The important principle is that repeated problems should not require entirely new decisions every time. Shared components and patterns allow teams to invest more effort once, then benefit from that work across future pages and products.
If your organization is trying to decide what level of system is appropriate, What is a Design System and does your organization need one? explores that distinction in more detail.
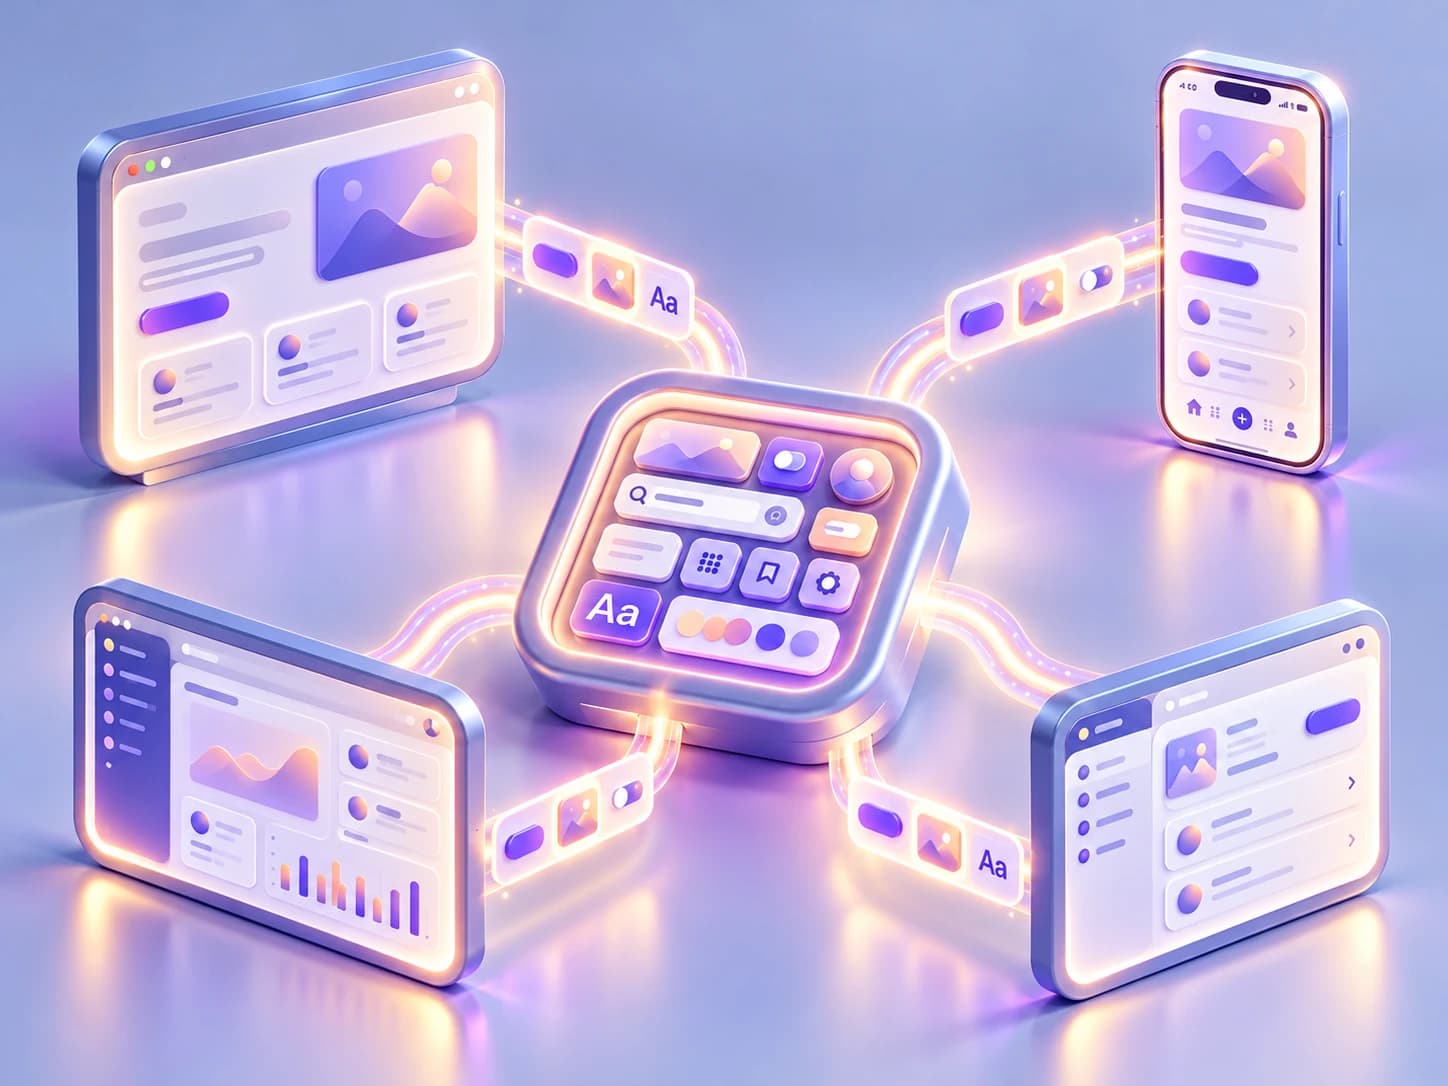
Reuse turns previous decisions into infrastructure, allowing limited teams to spend less time recreating familiar patterns and more time solving new problems.
Accessibility early saves remediation later
Accessibility is often one of the first areas organizations postpone when a project feels constrained. The assumption is that it can be audited near the end and whatever remains can be corrected before launch.
Some problems can be fixed that way. Others become much more expensive once they are embedded in the product.
A low-contrast color choice repeated across a component library can affect dozens of screens. An interaction pattern that cannot be used with a keyboard may require redesign rather than a small code adjustment. Poor heading structure can be corrected relatively easily, while an information architecture that makes content difficult to understand may require much deeper changes.
The earlier accessibility shapes visual design, content, interaction, and implementation, the less likely teams are to create barriers that later require remediation. This does not make accessibility valuable only because it can save money; accessibility is part of whether the product works for the people who need to use it. But from a resource perspective, preventing a structural problem is usually more efficient than discovering it after the same decision has propagated throughout the system.
That is why Why accessibility should be part of web design from day one argues for bringing accessibility into the product while decisions are still flexible. For organizations with limited resources, that flexibility is especially valuable because large rounds of rework are often exactly what the budget cannot absorb.
Choose boring technology when boring works
Technology decisions can become a source of unnecessary cost when novelty is mistaken for capability.
A mature CMS, a conventional server-rendered page, a standard form flow, or a widely supported framework may appear less exciting than a custom platform or a newer architectural pattern. That does not make it a weaker choice. In many cases, mature technology is easier to document, easier to hire for, easier to troubleshoot, and more predictable when the original development team is no longer involved.
The useful question is not whether a technology is modern enough. It is what additional complexity the organization is buying and which problem that complexity actually solves.
A custom CMS may be justified if the editorial workflow is genuinely unusual. A highly interactive client-side application may be appropriate when the product depends on complex real-time behavior. A specialized workflow engine may be valuable when the process itself requires sophisticated orchestration. But when a simpler tool already handles the need, additional architecture introduces dependencies that have to be maintained whether or not users benefit from them.
This matters because technical complexity rarely stays confined to the initial build. It affects upgrades, debugging, hiring, security, hosting, documentation, integrations, and the time required to make future changes.
For teams with limited technical capacity, predictable technology can be a strategic advantage. Choosing something well understood is not a lack of ambition when it gives the organization more control over the product it is creating.
Don't build what you can't maintain
Launch is only one moment in the life of a digital product. The decisions made during development continue to create work afterward.
Content needs to be updated. Dependencies change. Security issues appear. Integrations evolve. Accessibility needs to be checked as new features are added. Analytics need interpretation rather than merely installation. People need support. Bugs need triage. Staff members leave, and knowledge has to survive them.
A feature can therefore fit comfortably within the development budget and still be too expensive for the organization to own.
This is particularly important for features that depend on continuous attention. A directory that is useful only when every record is current creates an ongoing content obligation. A personalized recommendation system requires data, monitoring, and governance. A multilingual section creates translation and publishing work whenever content changes. An integration may create a permanent dependency on another vendor's API and pricing.
Maintenance belongs inside scope planning because these costs are part of the product, even if they happen after launch.
Before adding a capability, teams should understand who will own it, how often it needs attention, what happens when it breaks, and whether the organization is prepared to keep investing in it. Sometimes that analysis confirms that the feature is worth building. Sometimes it reveals that a simpler alternative will remain useful for much longer.
Measure before adding more
Once an initial product is live, the temptation to expand can return quickly. Stakeholders notice opportunities, users request features, and teams begin assembling another backlog.
Before adding more, it is worth observing what the existing product is actually doing.
Useful evidence does not always require a sophisticated analytics stack. A team can learn from completion rates on an important form, common search queries, support requests, frequently accessed resources, usability sessions, interviews, and recurring feedback from staff who work directly with users.
The point is to distinguish repeated needs from isolated requests and to understand where the current product is succeeding or failing before increasing its complexity.
If people are abandoning a critical form, adding a new dashboard elsewhere may not be the best next investment. If users consistently search for the same information, improving information architecture could create more value than launching another feature. If a section receives very little use, the answer may be to improve it, reposition it, or remove it rather than continue expanding it.
Measurement creates a feedback loop between investment and evidence. For organizations with limited resources, that loop is especially important because each new phase of work should ideally be informed by what the previous phase revealed.
Invest in foundations
Visible features are easy to describe in budgets and project plans. Foundations are less glamorous, but they often determine how expensive every future change will become.
Clear information architecture makes new content easier to place. Accessible components prevent teams from repeating the same remediation work. Good performance reduces the cost of delivering information across a wider range of devices and networks. Reusable patterns shorten design and development time. Maintainable code makes future changes safer. Documentation reduces dependence on individual team members. Appropriate analytics help the organization decide what deserves attention next.
These investments rarely appear to users as separate features, yet they influence the quality of almost everything users experience.
Strong foundations may be less visible than new features, but they reduce the cost and difficulty of every improvement that follows.
This is where limited resources can sometimes encourage better decisions. When a team cannot afford to rebuild repeatedly, it has a stronger reason to choose foundations that can support gradual growth. The goal is not to future-proof every possible requirement or build infrastructure for hypothetical scale. It is to avoid decisions that make the next useful change unnecessarily difficult.
Organizations with constrained budgets do not need to imitate the scope of much larger digital teams. They need to understand the problem they are solving now, build the smallest useful version with enough quality to be dependable, reuse what already works, and make technical and design choices they will still be able to support after launch.
That is a different kind of ambition. It does not measure progress by how many features were added. It measures whether the organization is building a digital product that can remain useful, understandable, and sustainable as needs evolve.
Keep reading
NGOs do not need to solve every accessibility issue at once. Start with critical services, set a baseline, stop creating new barriers and build a roadmap.
Accessibility
Accessibility debt: the problem nobody talks about
Accessibility debt builds up when an inaccessible decision repeats across components, content, code and processes. The longer it spreads, the more it costs.
If these challenges sound familiar, let’s talk about your context.
Start a conversation